
Power Up Your Study Prep: Black Friday 75% Discount! Use coupon code below to save! - Ends in 0d 00h 00m 00s - Coupon code: big75certs

Databricks Databricks-Certified-Professional-Data-Engineer Exam With Confidence Using Practice Dumps

Exam Code:
Databricks-Certified-Professional-Data-Engineer
Exam Name:
Databricks Certified Data Engineer Professional Exam
Certification:
Vendor:
Questions:
285
Last Updated:
Nov 21, 2026
Exam Status:
Stable
Databricks Databricks-Certified-Professional-Data-Engineer

Databricks-Certified-Professional-Data-Engineer: Databricks Certification Exam 2025 Study Guide Pdf and Test Engine

Are you worried about passing the Databricks Databricks-Certified-Professional-Data-Engineer (Databricks Certified Data Engineer Professional Exam) exam? Download the most recent Databricks Databricks-Certified-Professional-Data-Engineer braindumps with answers that are 100% real. After downloading the Databricks Databricks-Certified-Professional-Data-Engineer exam dumps training , you can receive 99 days of free updates, making this website one of the best options to save additional money. In order to help you prepare for the Databricks Databricks-Certified-Professional-Data-Engineer exam questions and verified answers by IT certified experts, CertsTopics has put together a complete collection of dumps questions and answers. To help you prepare and pass the Databricks Databricks-Certified-Professional-Data-Engineer exam on your first attempt, we have compiled actual exam questions and their answers. 

Our (Databricks Certified Data Engineer Professional Exam) Study Materials are designed to meet the needs of thousands of candidates globally. A free sample of the CompTIA Databricks-Certified-Professional-Data-Engineer test is available at CertsTopics. Before purchasing it, you can also see the Databricks Databricks-Certified-Professional-Data-Engineer practice exam demo.

Databricks Certified Data Engineer Professional Exam Questions and Answers

Question 1

A junior data engineer is working to implement logic for a Lakehouse table named silver_device_recordings. The source data contains 100 unique fields in a highly nested JSON structure.

The silver_device_recordings table will be used downstream to power several production monitoring dashboards and a production model. At present, 45 of the 100 fields are being used in at least one of these applications.

The data engineer is trying to determine the best approach for dealing with schema declaration given the highly-nested structure of the data and the numerous fields.

Which of the following accurately presents information about Delta Lake and Databricks that may impact their decision-making process?

Options:

A.

The Tungsten encoding used by Databricks is optimized for storing string data; newly-added native support for querying JSON strings means that string types are always most efficient.

B.

Because Delta Lake uses Parquet for data storage, data types can be easily evolved by just modifying file footer information in place.

C.

Human labor in writing code is the largest cost associated with data engineering workloads; as such, automating table declaration logic should be a priority in all migration workloads.

D.

Because Databricks will infer schema using types that allow all observed data to be processed, setting types manually provides greater assurance of data quality enforcement.

E.

Schema inference and evolution on .Databricks ensure that inferred types will always accurately match the data types used by downstream systems.

Buy Now
Question 2

The data engineering team has configured a job to process customer requests to be forgotten (have their data deleted). All user data that needs to be deleted is stored in Delta Lake tables using default table settings.

The team has decided to process all deletions from the previous week as a batch job at 1am each Sunday. The total duration of this job is less than one hour. Every Monday at 3am, a batch job executes a series of VACUUM commands on all Delta Lake tables throughout the organization.

The compliance officer has recently learned about Delta Lake's time travel functionality. They are concerned that this might allow continued access to deleted data.

Assuming all delete logic is correctly implemented, which statement correctly addresses this concern?

Options:

A.

Because the vacuum command permanently deletes all files containing deleted records, deleted records may be accessible with time travel for around 24 hours.

B.

Because the default data retention threshold is 24 hours, data files containing deleted records will be retained until the vacuum job is run the following day.

C.

Because Delta Lake time travel provides full access to the entire history of a table, deleted records can always be recreated by users with full admin privileges.

D.

Because Delta Lake's delete statements have ACID guarantees, deleted records will be permanently purged from all storage systems as soon as a delete job completes.

E.

Because the default data retention threshold is 7 days, data files containing deleted records will be retained until the vacuum job is run 8 days later.

Question 3

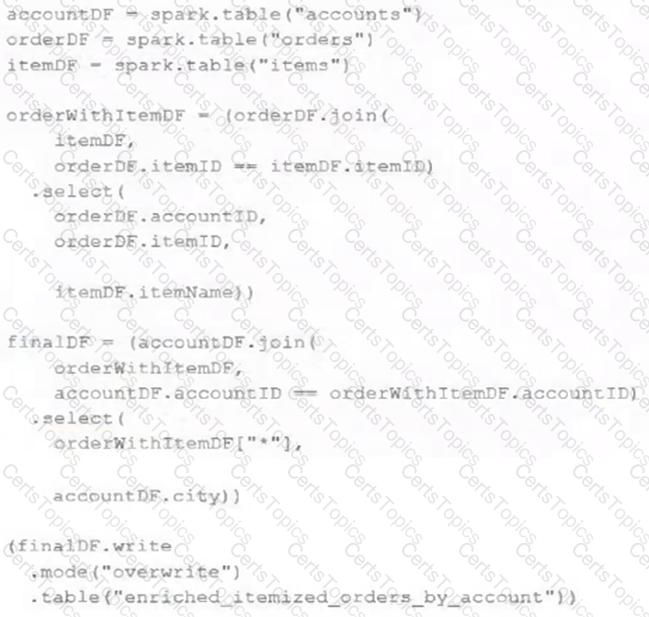
The data engineering team maintains the following code:

Assuming that this code produces logically correct results and the data in the source tables has been de-duplicated and validated, which statement describes what will occur when this code is executed?

Options:

A.

A batch job will update the enriched_itemized_orders_by_account table, replacing only those rows that have different values than the current version of the table, using accountID as the primary key.

B.

The enriched_itemized_orders_by_account table will be overwritten using the current valid version of data in each of the three tables referenced in the join logic.

C.

An incremental job will leverage information in the state store to identify unjoined rows in the source tables and write these rows to the enriched_iteinized_orders_by_account table.

D.

An incremental job will detect if new rows have been written to any of the source tables; if new rows are detected, all results will be recalculated and used to overwrite the enriched_itemized_orders_by_account table.

E.

No computation will occur until enriched_itemized_orders_by_account is queried; upon query materialization, results will be calculated using the current valid version of data in each of the three tables referenced in the join logic.